Benchmark · v1, October 2026
Which AI assistants search the web before they answer?
When someone asks an AI assistant about software, does it look on the web first, or answer from what it already knows?
Only tests we ran ourselves, never what makers claim.
- runs counted
- 74
- assistants ranked
- 4
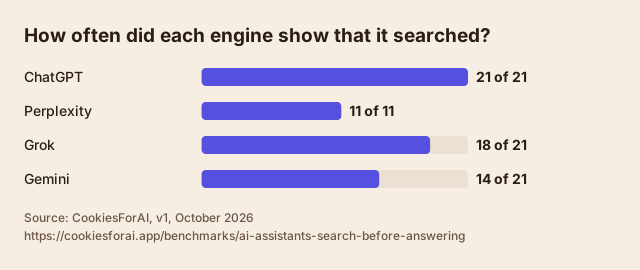
How often did each engine show that it searched?
- ChatGPT21 of 21
- Perplexity11 of 11
- Grok18 of 21
- Gemini14 of 21
Main runs where ChatGPT showed web citations, Perplexity searched, and Gemini (3.6 Flash) and Grok showed sources, on . Google AI Mode and AI Overviews are not ranked here: they were search-grounded in all 34 runs we logged (21 AI Mode, 13 AI Overviews).
Source: CookiesForAI, v1, October 2026
Higher is better
Reuse this chart
Free to reuse with credit (CC BY 4.0). Download SVG
<figure><img src="https://cookiesforai.app/charts/benchmark--ai-assistants-search-before-answering.svg" alt="How often did each engine show that it searched: ChatGPT 21 of 21, Perplexity 11 of 11, Grok 18 of 21, Gemini 14 of 21."><figcaption>Source: CookiesForAI, How often did each engine show that it searched?, https://cookiesforai.app/benchmarks/ai-assistants-search-before-answering</figcaption></figure>The ranking
| Rank | Name | Score | Date | Study |
|---|---|---|---|---|
| 1 | ChatGPTModel as shown: gpt-5-6, then gpt-5-6-mini | 100%21 of 21 | Read the study | |
| 1 | PerplexityModel as shown: not shown | 100%11 of 11 | Read the study | |
| 3 | GrokModel as shown: Grok (Fast) | 86%18 of 21 | Read the study | |
| 4 | GeminiModel as shown: Gemini 3.6 Flash | 67%14 of 21 | Read the study |
What changed
- : First edition, from the runs of .
All editions
- v1, October 2026: runs of , published
Data and how to cite
Download the data: CSV (every chart of the study, this one included). Free to reuse with credit (CC BY 4.0).
CookiesForAI, "Which AI assistants search the web before they answer?", benchmark, v1, October 2026, https://cookiesforai.app/benchmarks/ai-assistants-search-before-answering/2026-10-01Questions people ask
How do we choose what goes on a scoreboard?
Only tests we ran ourselves and published as a study, with the questions, the dates, the number of runs and the data. A board takes its numbers straight from the study's chart, so the two can never differ. We do not rank directories or other websites.
Why can our numbers differ from what makers say?
Makers usually test their own setup, with their own questions. We type real questions into the chat apps in the browser, or into Claude Code with web search on, as anyone could, on a stated day, and count what we saw. A different day, account, model or wording can give a different count, which is why every board names where it ran and the day of the runs.
What does "N of M" mean, and why do small samples matter?
M is how many runs we made and N is how many of them passed the test; each run gives one answer. The rank comes from N divided by M, and rows with the same share get the same rank. With a few dozen runs per row, a gap of one or two runs can be chance, so read close scores as close, not as a clear win.
Do we have an interest of our own?
CookiesForAI lists agent skills, MCP servers and apps, so our own pages can appear in these answers; when they do, we count them like any other site.
How do I send a correction?
Write to us with the board, the row and what you think is wrong. We check it against the saved runs and fix the board. Contact us.